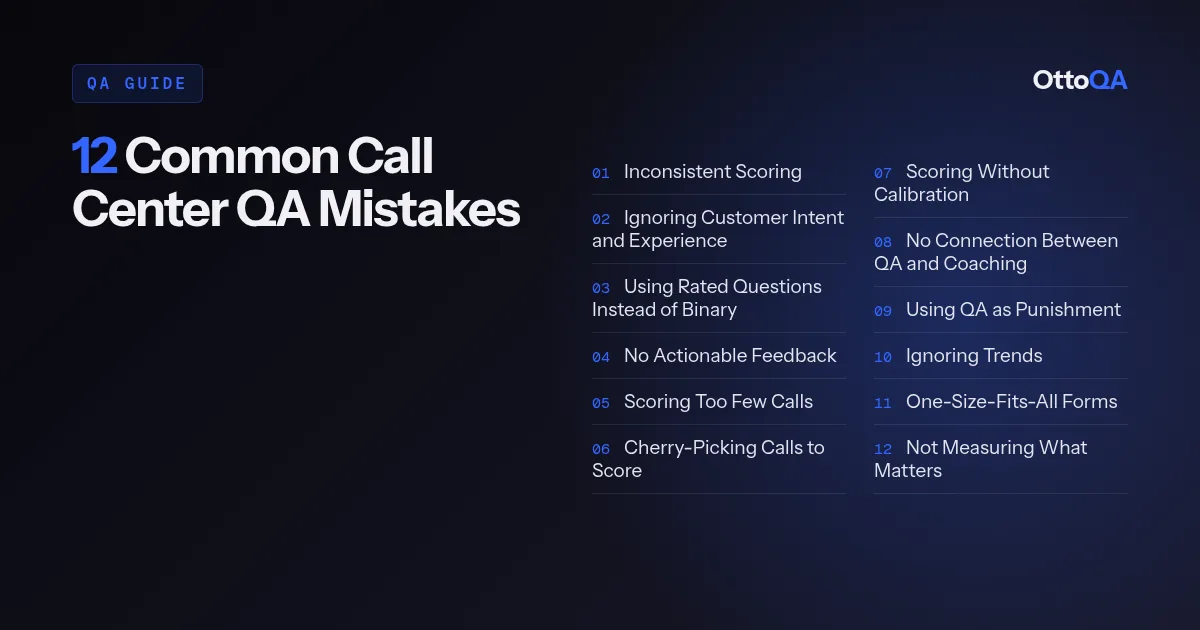
Updated October 2026. Most QA programs don't fail for lack of effort. They fail because of a handful of habits that make scores inconsistent and coaching vague. Here are the 12 mistakes we see most and how to fix each one.
1. Inconsistent scoring
Two evaluators score the same call differently, and agents stop trusting the number.
Fix: Write a definition and an example for every question on the scorecard, and hold regular calibration sessions where evaluators score the same call and talk through every disagreement.
2. Ignoring customer intent
Forms that only check script steps push agents to recite instead of solve.
Fix: Add questions on whether the customer's actual problem was solved, not just whether the steps were followed.
3. Rated questions instead of binary
A 1-to-5 scale means something different to every evaluator.
Fix: Use more yes/no questions. "Did the agent acknowledge the concern before moving to resolution?" is clearer than "Rate empathy 1-5."
4. Scores with no actionable feedback
A number alone doesn't tell an agent what to change.
Fix: Point to the specific moment in the call that worked or didn't, and review it one-on-one.
5. Scoring too few calls
Most QA teams only score a small sample of calls, so coaching rests on anecdotes.
Fix: Set a sampling plan that is large enough to see patterns per agent, or use AI QA to score far more of your calls against your own form.
6. Cherry-picking calls
Picking calls by length, complaints or gut feel biases the data.
Fix: Use stratified random sampling across agents, call types and times of day.
7. Skipping calibration
Without calibration, evaluator standards drift over time.
Fix: Calibrate on a fixed schedule. If you use AI scoring, calibrate it too: have people score a set of calls and compare them with the AI's answers.
8. No link between QA and coaching
Scores that sit in a spreadsheet change nothing.
Fix: Tie each coaching session to specific scored calls and agree on one or two behaviors to work on.
9. Using QA as punishment
When agents fear QA, they game it.
Fix: Frame QA as development. Recognize strong calls and use low scores as coaching opportunities.
10. Ignoring trends
Single-call scores are useful; patterns across many calls are what change a team.
Fix: Review results weekly and monthly by agent, team and call type.
11. One form for every call type
Sales and support calls need different skills.
Fix: Build a separate form for each call type, with questions that match its goals.
12. Measuring what doesn't matter
"Used the customer's name three times" rarely predicts satisfaction. "Solved the problem on the first call" usually does.
Fix: Check each question against an outcome such as CSAT, FCR or revenue. Our free QA Form Analyzer shows where a form needs work.
Where AI QA fits
OttoQA scores calls against each client's own QA form, with 96% accuracy, and connects to CCaaS platforms through API integrations. There are no seat licenses and no IT project, and you can be live in days. The one-time $1,000 covers setup and a 200 to 500 call proof of concept. Book a 30-minute demo.
Related reading
- How many calls should QA score?
- How many QA evaluations per agent
- The ultimate guide to call center quality assurance
- Free QA Form Analyzer
- Free Erlang A calculator (Erlang C too): staff the queue before you blame the agent. Agents running near 100% occupancy skip steps.